
The previous article, "3 Simple Steps to Migrate Your Database to GCP," covered migration procedures. This article defines steps for building a data pipeline on Google Cloud Platform (GCP). These steps cover ingestion, transformation, and analysis to support data-driven operations.
Function of Data Pipelines in Data Architecture
Data pipelines process large volumes of data. Businesses generate data from IoT devices, applications, and third-party APIs. Pipelines ingest, transform, and store data in structured formats. This structure supports analytics and decision-making.
Build a GCP Data Pipeline in Three Steps
Execute these three steps to build a data pipeline on GCP:
1. Ingest Data in Real Time with Pub/Sub
Google Cloud Pub/Sub provides managed messaging for real-time ingestion. It decouples systems and applications. This design supports high-throughput data from sources such as clickstreams and IoT signals. Pub/Sub scales automatically with data volume. This removes the need for capacity planning. The service handles continuous data streams.
Key Actions:
- Create topics and subscriptions in Pub/Sub.
- Configure data sources to publish messages to the Pub/Sub topic.
- Define handling for message failures, retries, and acknowledgments.
Pub/Sub enables efficient data ingestion. This approach minimizes data loss during high-volume operations.
2. Data Transformation with Dataflow
Process and transform data in Google Cloud Dataflow after ingestion into Pub/Sub. This fully managed service supports batch and stream processing using the Apache Beam framework.
Actions:
- Create a Dataflow job to consume Pub/Sub messages.
- Define ETL tasks. Tasks clean data, add metadata, or aggregate data for reports.
- Enable auto scaling to match data volume.
Pub/Sub and Dataflow form a scalable pipeline for real-time data processing. This architecture provides current insights for business operations.
3. Store and analyze data in BigQuery
Store transformed data in Google BigQuery, a managed data warehouse. BigQuery uses fast SQL queries for real-time analytics. It integrates directly with Dataflow to load processed data into tables. This setup supports complex queries that inform business decisions.
Key actions:
- Create a BigQuery dataset and table schema for processed data.
- Write the Dataflow output to BigQuery via the WriteToBigQuery connector.
- Query the data with BigQuery native functions or connect BigQuery to a business intelligence tool, such as Data Studio, to build dashboards and reports.
Store transformed data in BigQuery to support low-latency queries and analysis. This enables real-time, data-driven decision making.
Use Case
- An e-commerce platform requires real-time insights from clickstream data. It uses these insights to analyze user behavior, optimize site features, and improve product recommendations. Real-Time Analytics for E-commerce Clickstream Data
- Manufacturing companies analyze IoT sensor data to monitor equipment health and predict maintenance needs. This pipeline processes sensor inputs to identify failure patterns.
- Financial services firms use pipelines to analyze real-time transaction data. This process identifies fraudulent activity and reduces risk exposure.
Summary
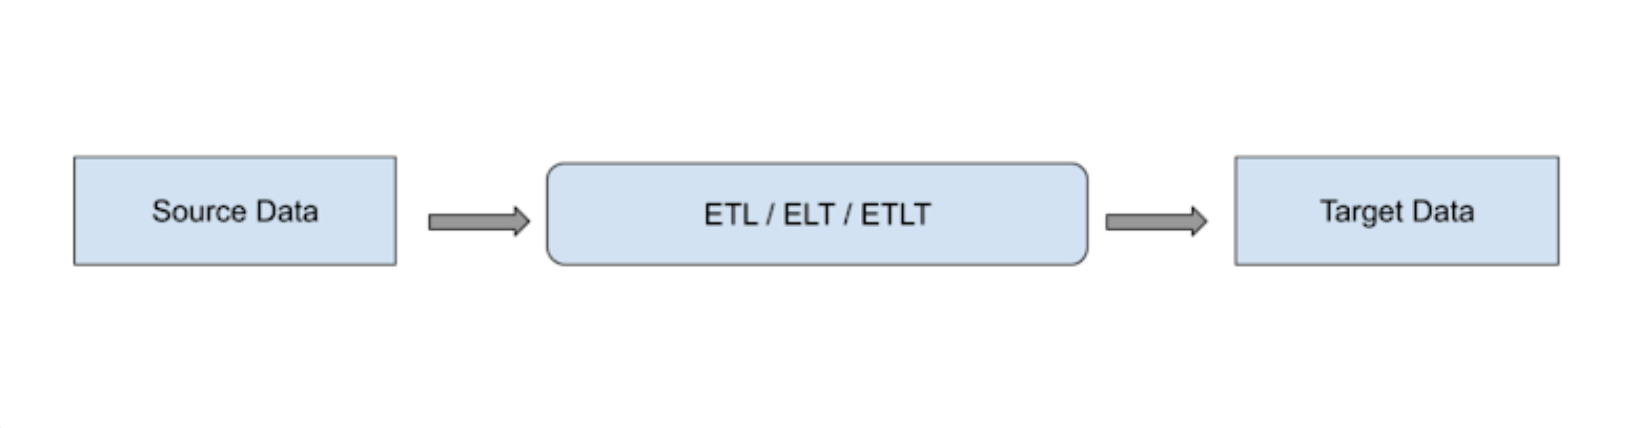
A GCP data pipeline moves data from ingestion to analysis efficiently.
- Use Pub/Sub for real-time ingestion.
- Use Dataflow for transformation.
- Use BigQuery for storage.
This setup provides a scalable and cost-effective solution.
Apply best practices to build a robust pipeline.
For help building a data pipeline on Google Cloud, see our data engineering services.
Related reading: GCP data engineering tools and their benefits.
- Handle diverse workloads.
- Improve insight accuracy and speed.
- Maintain a competitive position in data-driven markets.